F878 — Deep Reasoning Core
F878 covers “Deep Reasoning Core”. The canonical record classifies it as failed/revert, based on 2 source artifacts and 1 original source figure. The highlighted measurements are Reasoning cycle used = 0.083, Subquestions created = 0.067, and Evidence support = 0.000.
Purpose and research question
F878 evaluated whether the deep-reasoning cycle was actually used across subquestion creation, evidence support, contradiction checks, self-evaluation, why questions, multi-step prompts, follow-ups, and structured traces.
Method
F878 measured use and correctness separately across the deep-reasoning cycle: subquestion creation, evidence support, contradiction checks, self-evaluation blocking, why questions, multi-step prompts, follow-ups, and trace fields. Passing hygiene checks such as 0.900 self-evaluation blocking were kept separate from the failed usage, evidence, correctness, and completion gates.
Documentation basis
2 source artifacts and 1 phase-specific figure are recorded for this phase.
Evidence highlights
- Deep-reasoning cycle used: 0.083
- Evidence support used: 0.000
- Why questions correct: 0.000
- Multi-step reasoning: 0.200
- Module completion: 0.000
- Decision: REVERT_OR_FIX
Recorded evidence
| Reasoning cycle used | 0.083 |
|---|---|
| Subquestions created | 0.067 |
| Evidence support | 0.000 |
| Why questions correct | 0.000 |
| Multi-step reasoning | 0.200 |
| Self-eval blocking | 0.900 |
Public evidence and source figures
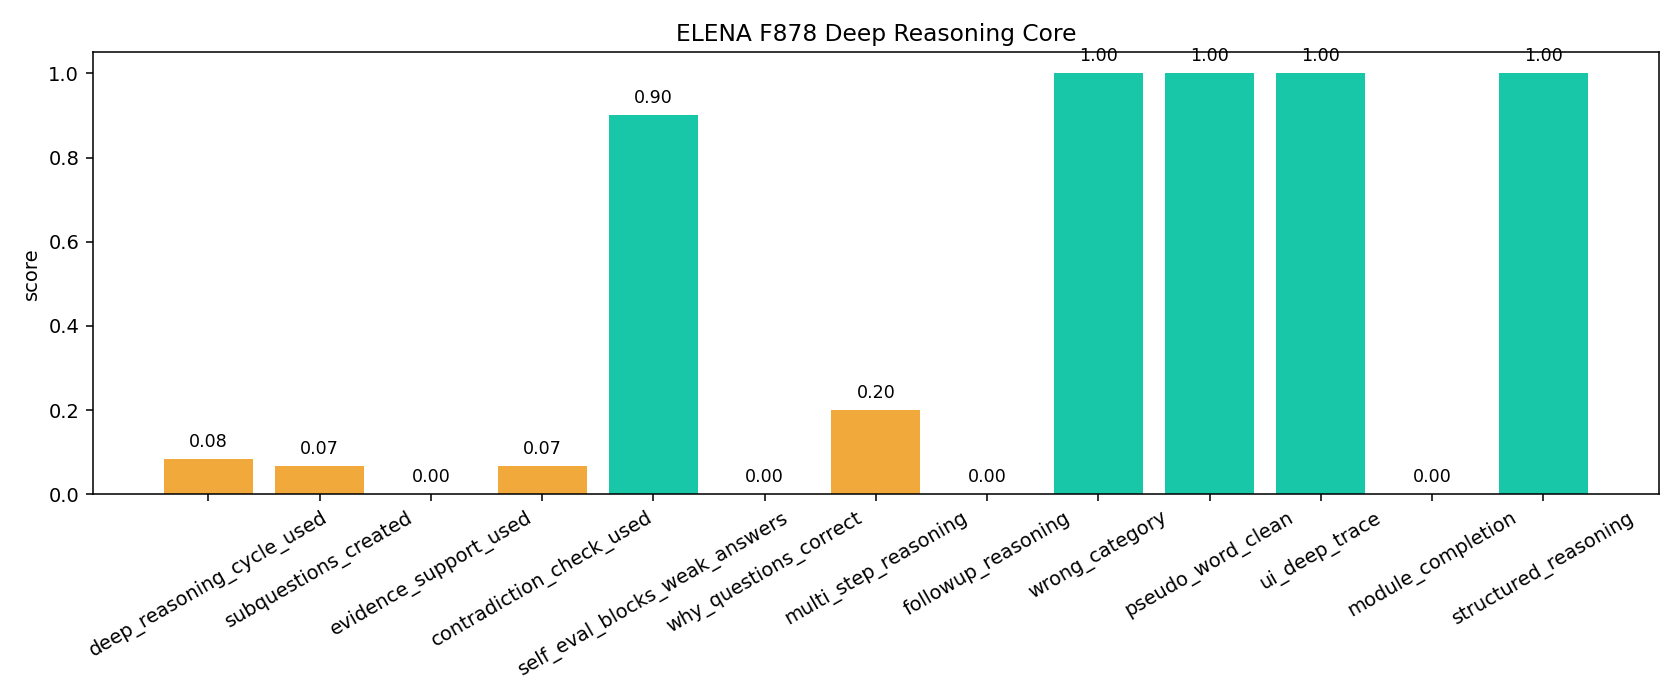
Original source figure · 1680 × 700 px
These are original source figures from the existing public evidence set, not editorial HTML visualizations.
Result and interpretation
The deep-reasoning cycle was used at 0.083, subquestions at 0.067, evidence support at 0.000, and contradiction checks at 0.067. Why-question and follow-up correctness were 0.000, multi-step reasoning was 0.200, and module completion was 0.000. The gate failed with REVERT_OR_FIX.
Key results
- Reasoning cycle used
- 0.083
- Subquestions created
- 0.067
- Evidence support
- 0.000
- Why questions correct
- 0.000
- Multi-step reasoning
- 0.200
- Self-eval blocking
- 0.900
Evidence sources
Values on this page are reproduced from the archived phase record and the source artifacts below. No new benchmark was run to create this page.
- DEEP REASONING CORE 878 (JSON)
- DEEP REASONING CORE 878 (MD)